RealMe : Immersive Volumetric Video from Minimal Captures
 SIGGRAPH Asia 2026
 Paper
 arXiv
 Code
 Data
TL;DR
- RealMe turns sparse, low-resolution multi-view captures into 2K, 4D-consistent volumetric video.
- We adapt a high-resolution diffusion prior for 4D enhancement, with frequency guidance to recover fine details.
- We create RealVV, a self-captured multi-view dataset for challenging capture settings.
Demo Video
Method
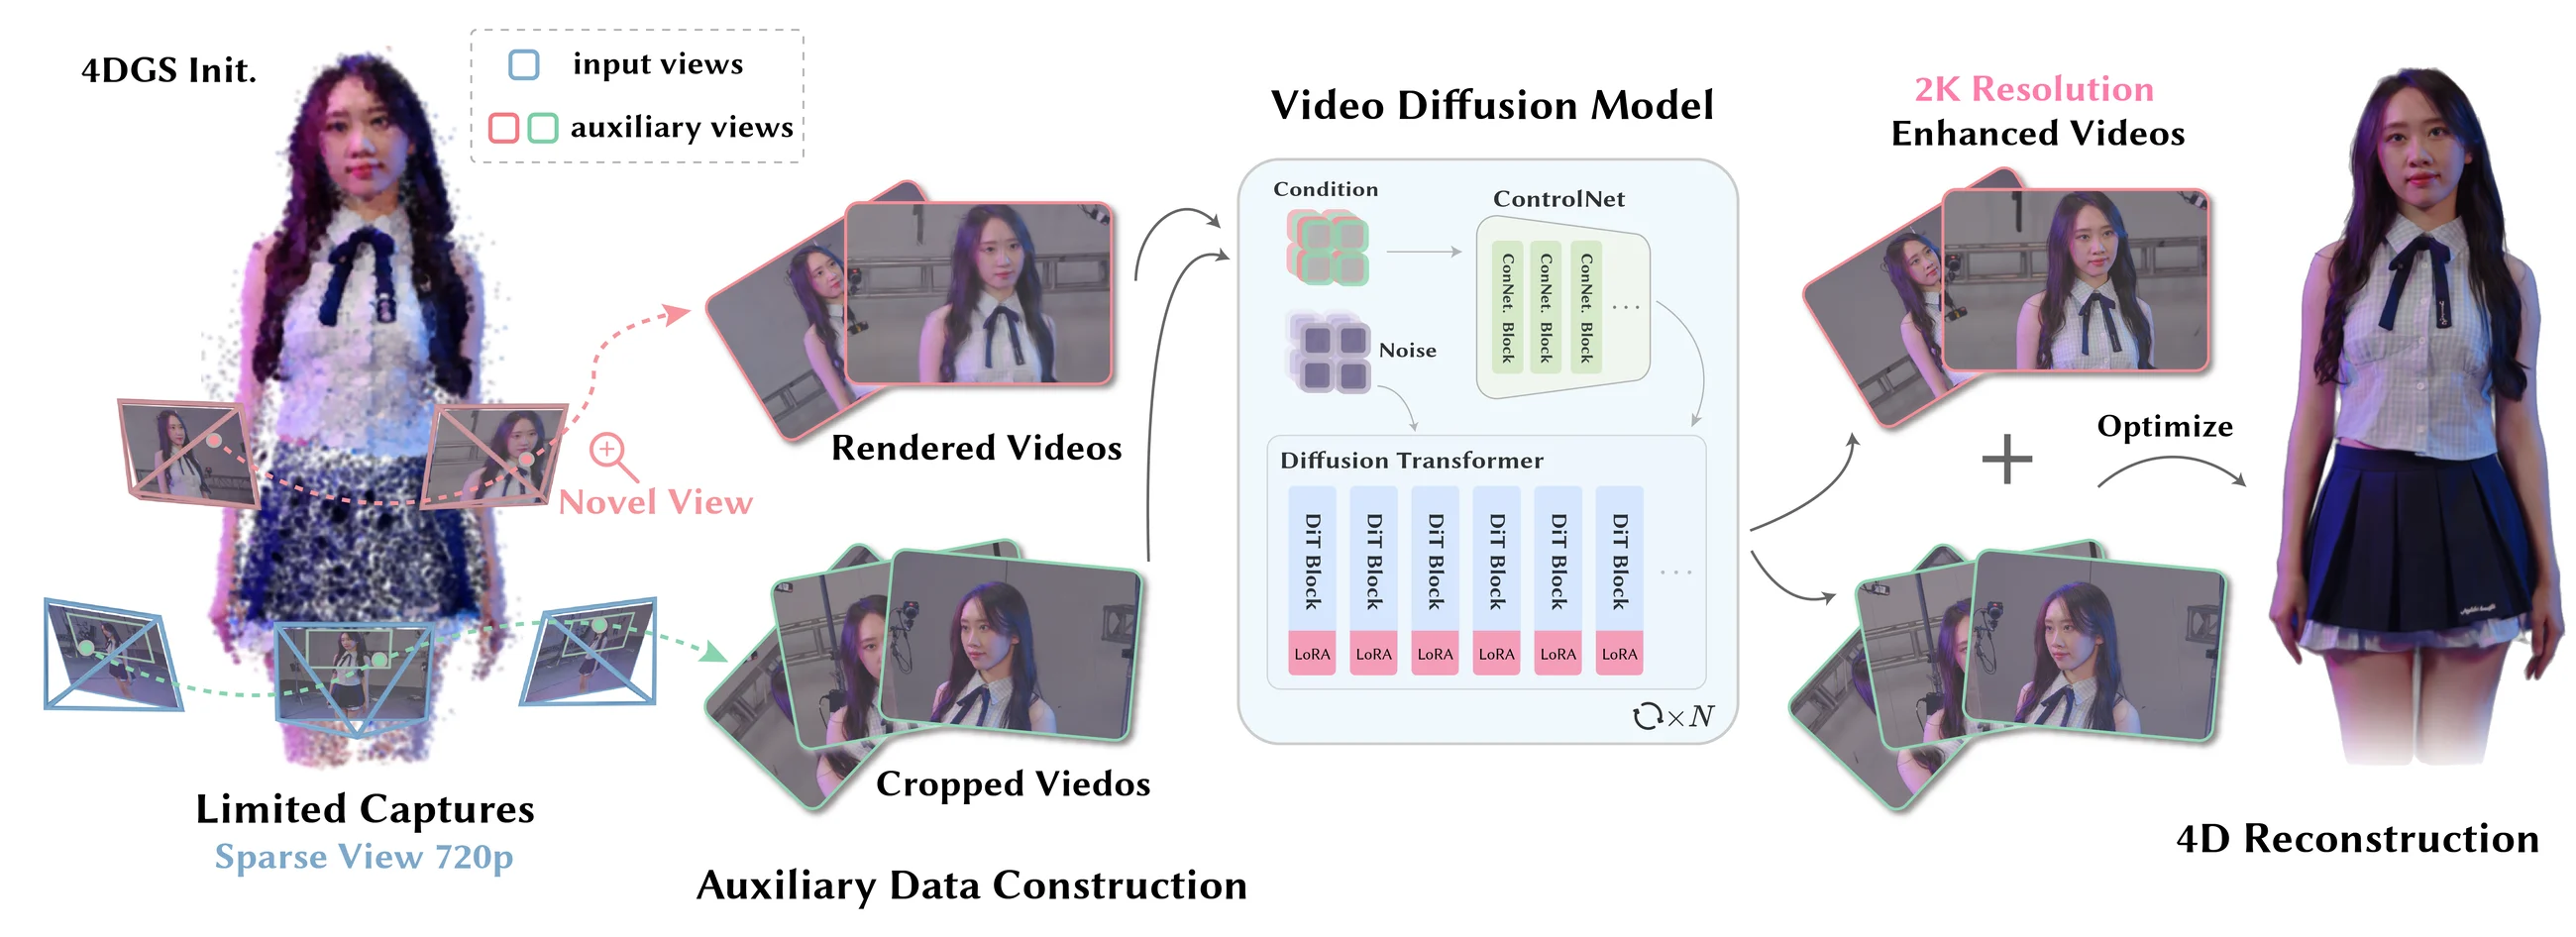
Pipeline overview. From sparse, low-resolution (720p) multi-view captures, RealMe builds a coarse 4D representation and creates auxiliary videos from novel-view renders and crops of the inputs. Conditioned on these auxiliary videos, a high-resolution video diffusion model generates enhanced videos that are used together with the original captures to optimize the final 4D representation.
Model Architecture
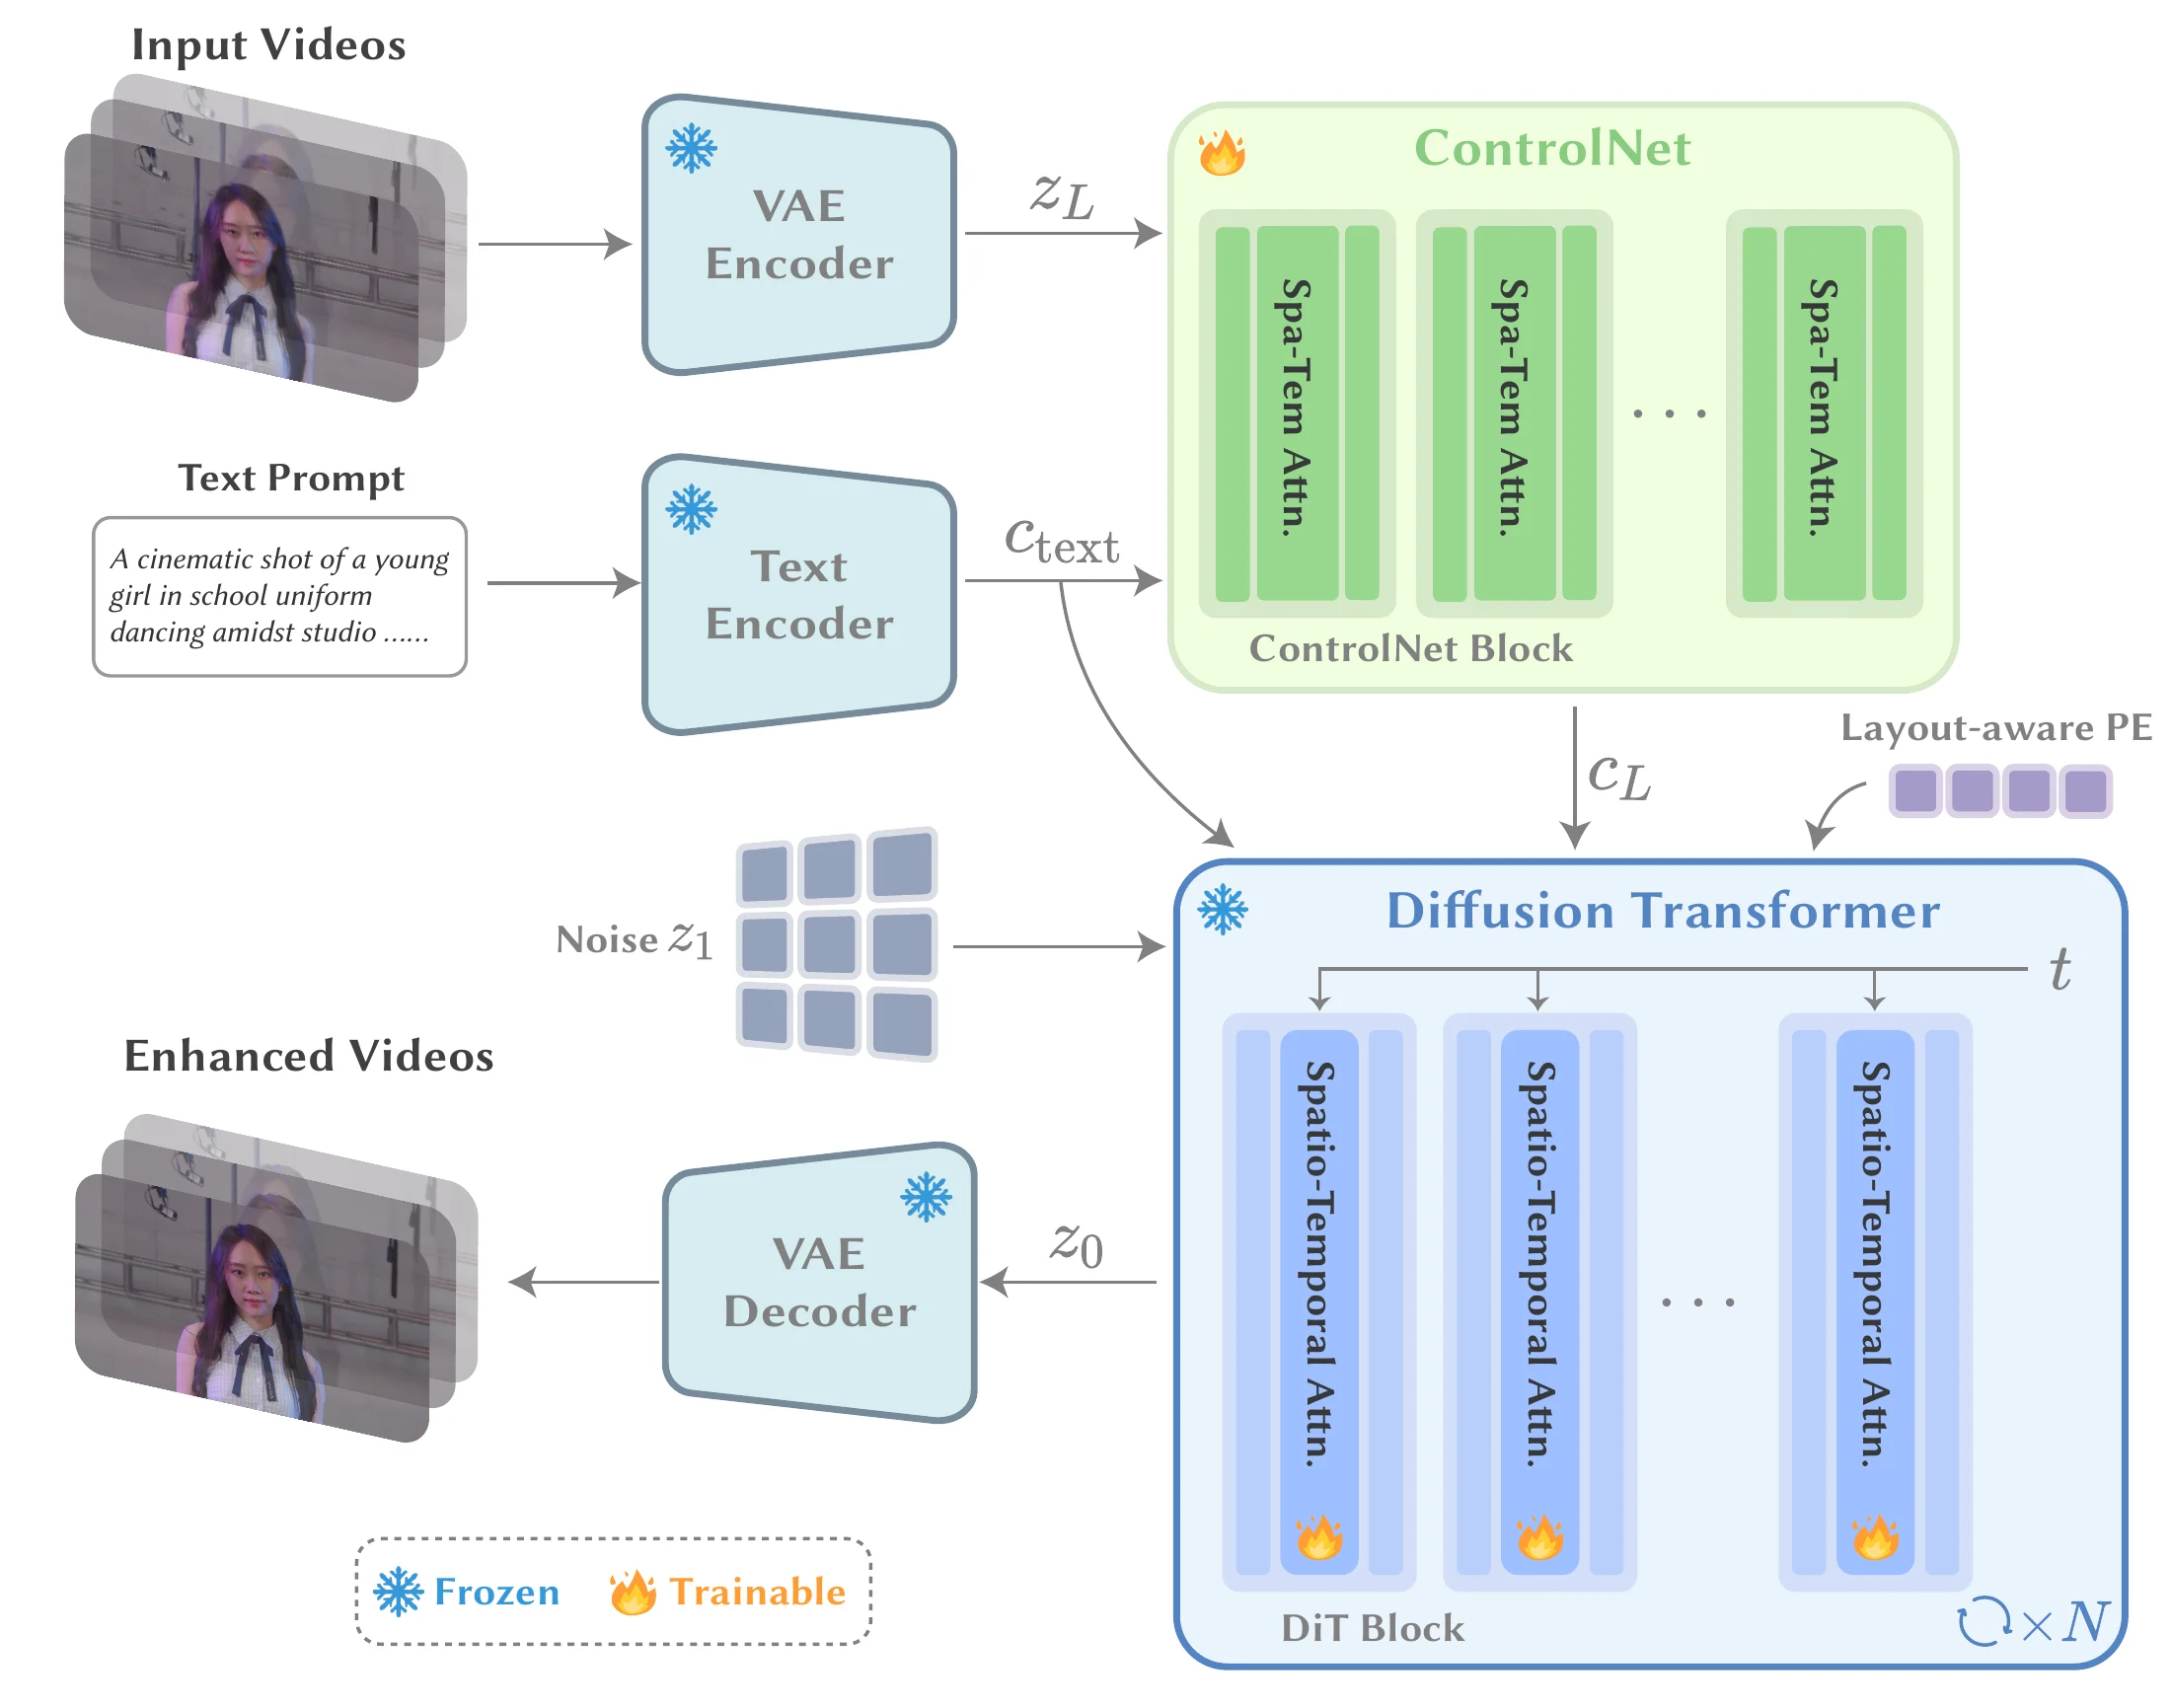
- ControlNet. A frozen VAE encodes the auxiliary videos into condition latents, while a frozen text encoder provides prompt features. ControlNet converts both into control signals injected as conditioning residuals into each DiT block.
- Layout-aware positional embeddings. We extend image positional IDs with frame and viewpoint indices alongside the two latent-grid coordinates. Rotary embeddings over these four axes distinguish tokens at the same grid location across different frames and views.
- DiT with factorized spatio-temporal attention. DiT blocks replace full attention with separate temporal and spatial patterns, where the spatial axis indexes viewpoints rather than image patches. This propagates information across frames and views during denoising, improving 4D consistency.
Comparisons
RealMe outperforms state-of-the-art methods in novel-view synthesis quality and 4D consistency on both datasets.
Detail comparison
Indoor capture
Zoom in for a better view
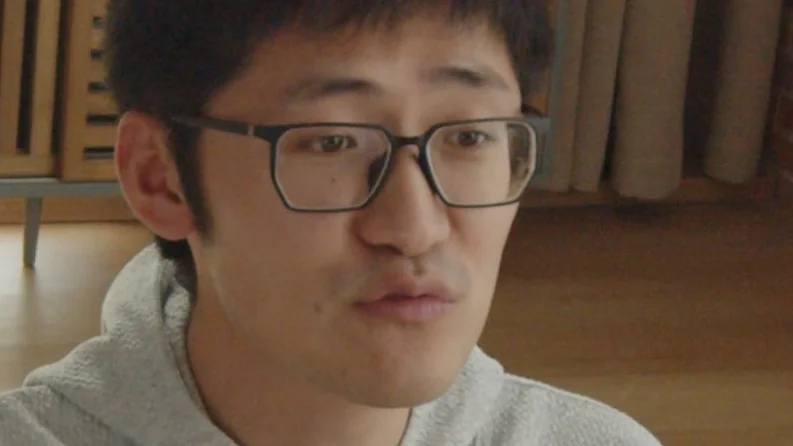
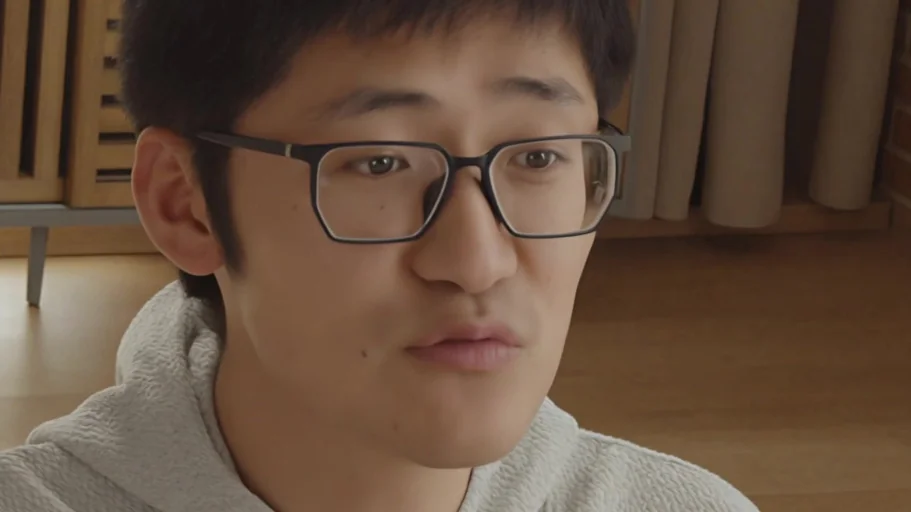
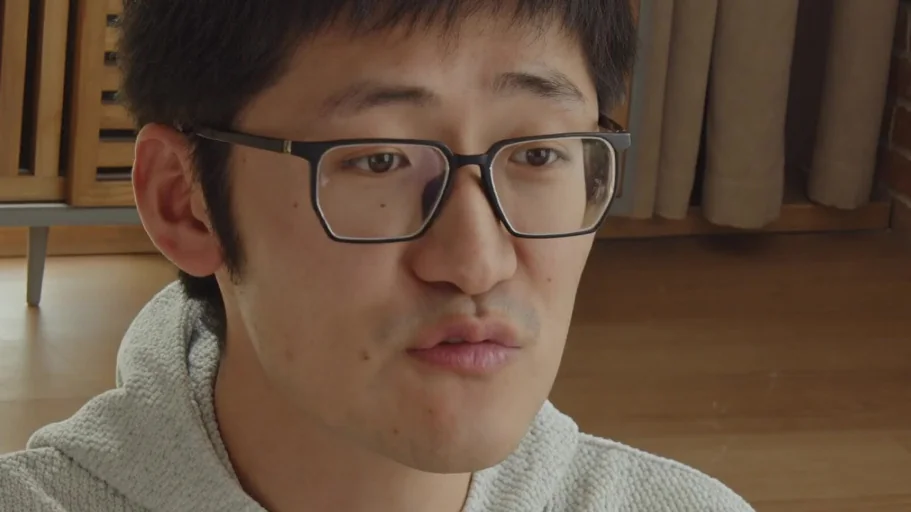
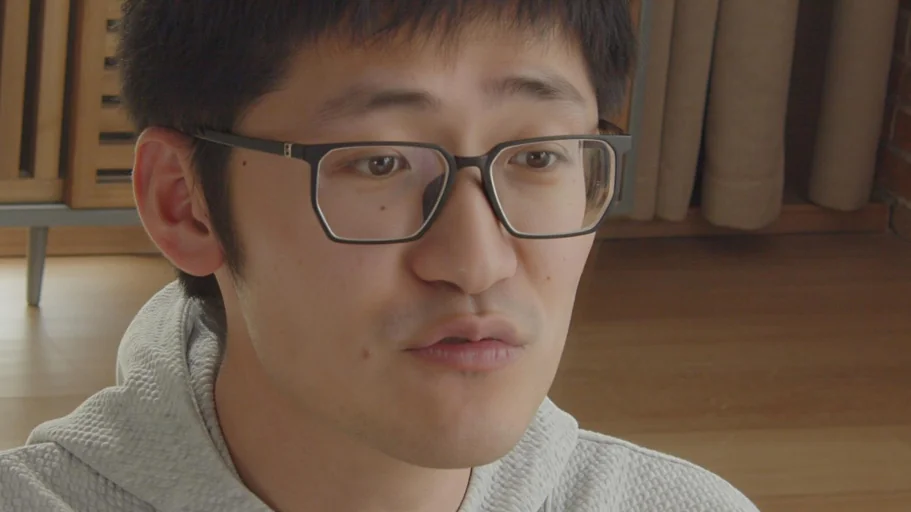
Studio capture
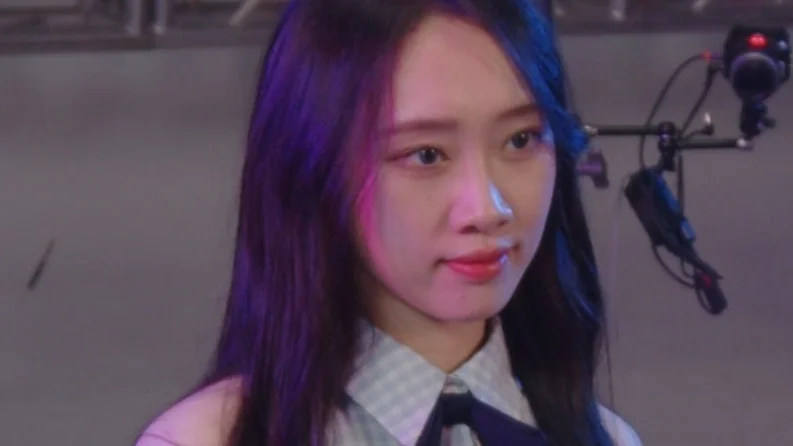
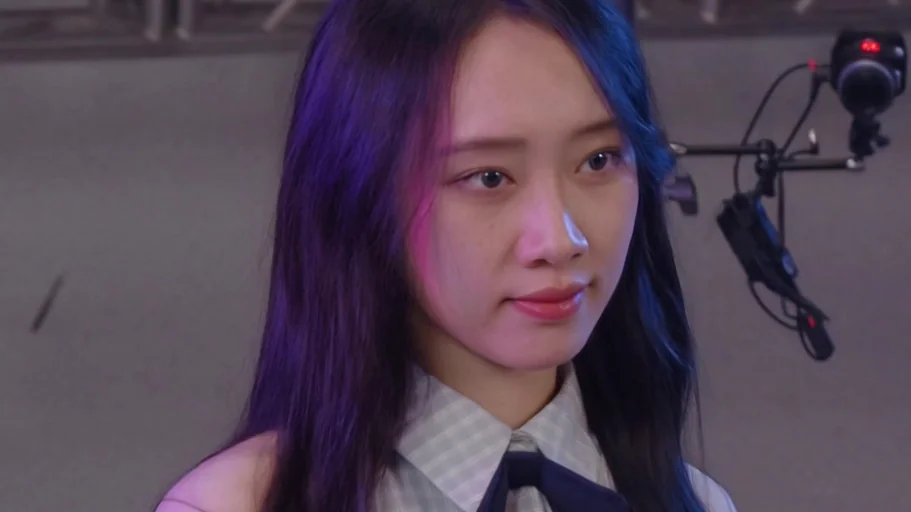
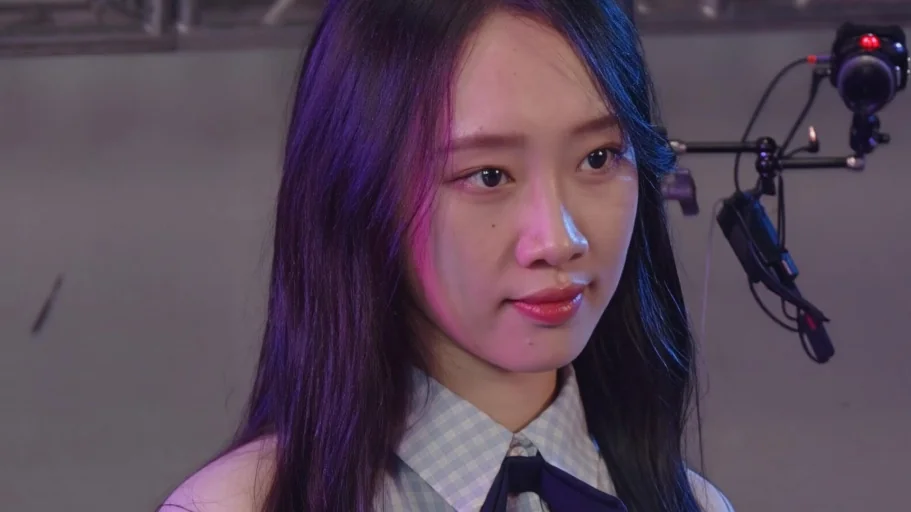
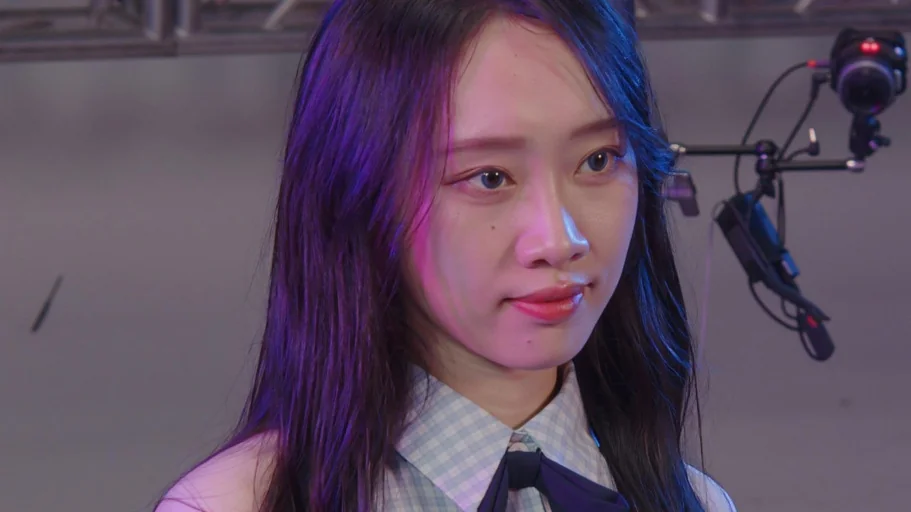
Compared with STAR and FlashVSR, RealMe restores finer facial, hair, and clothing detail with a more natural appearance.
RealVV Dataset
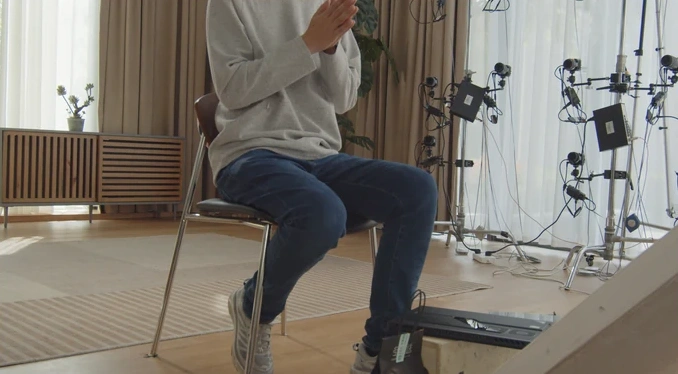
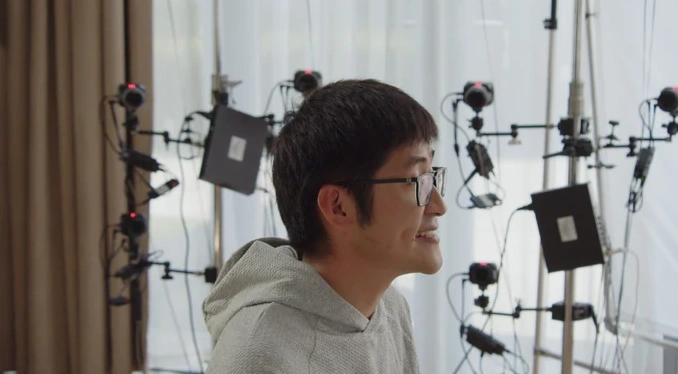
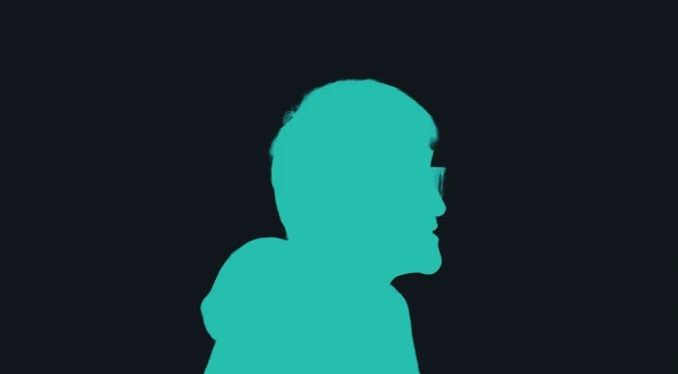
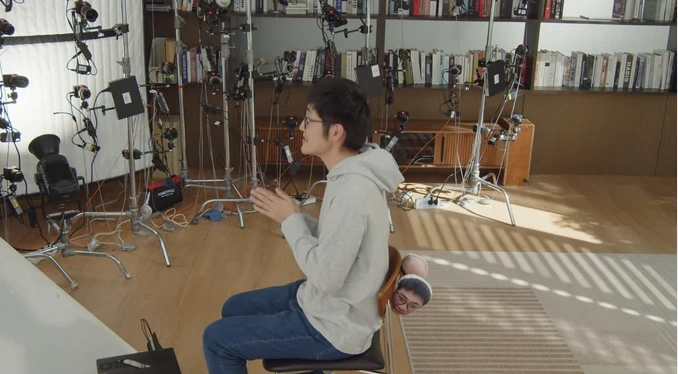
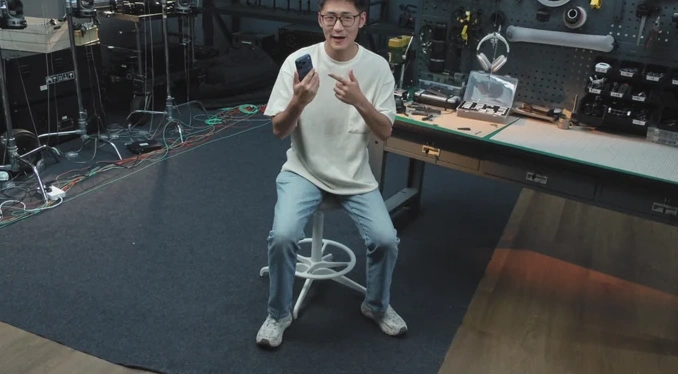
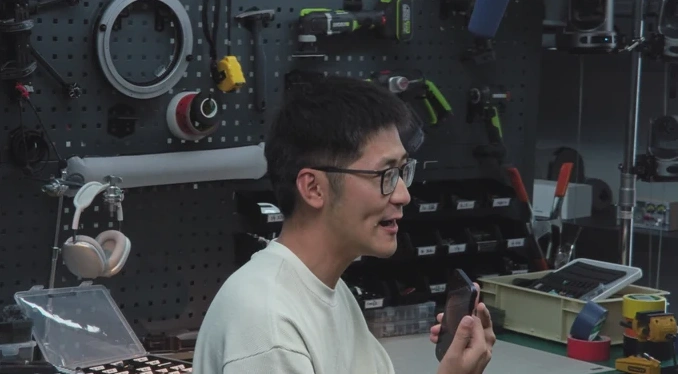
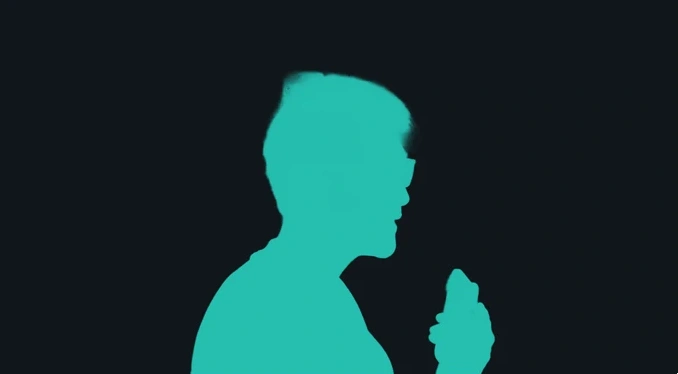
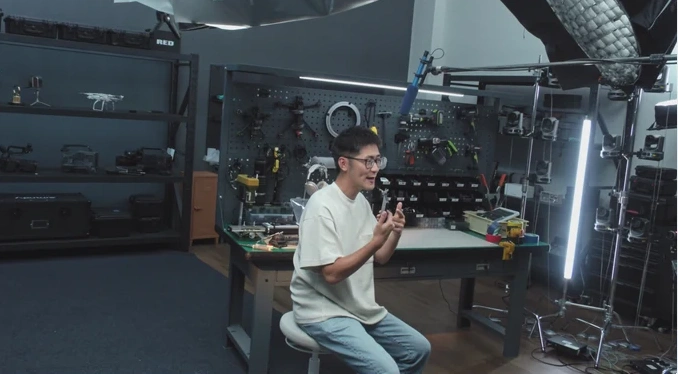
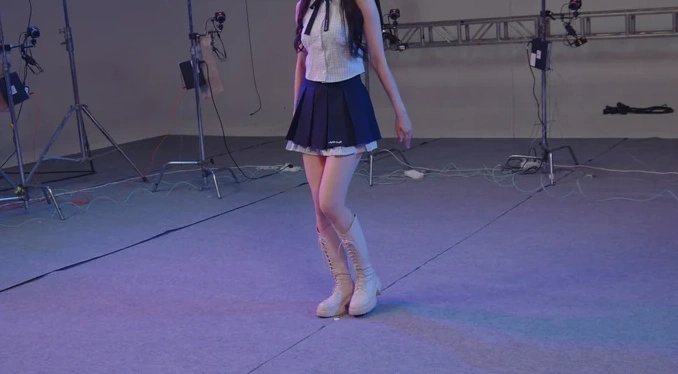
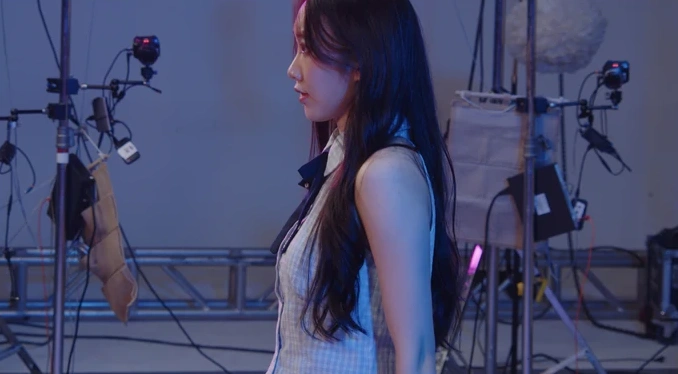
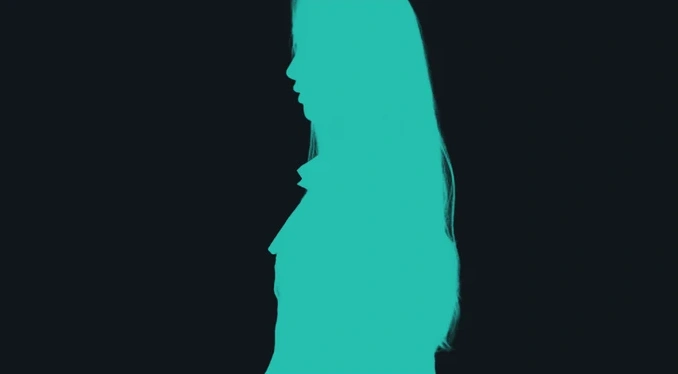
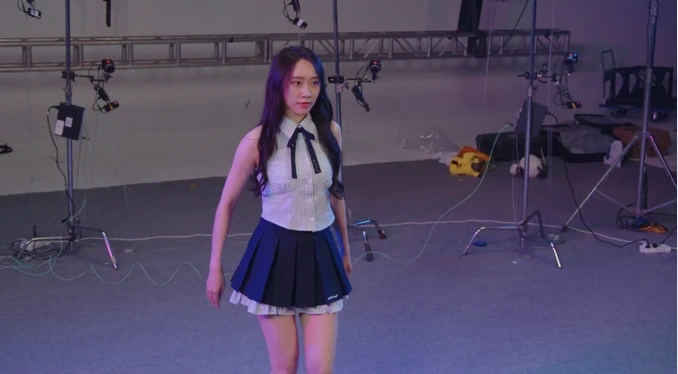
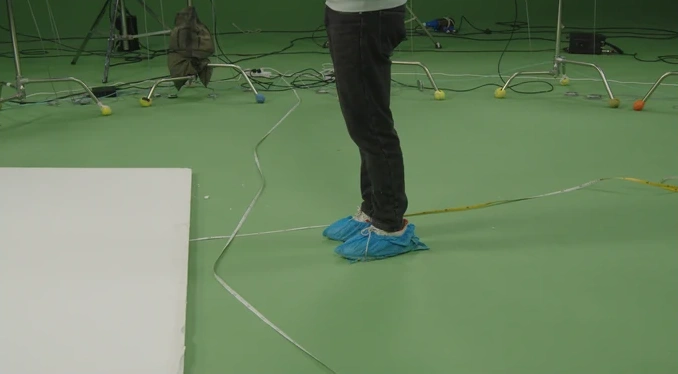
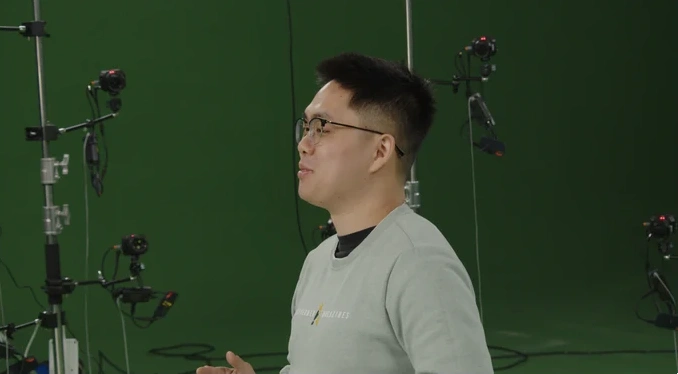
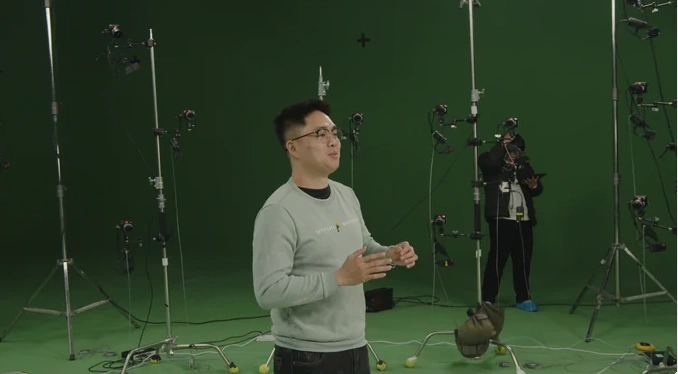
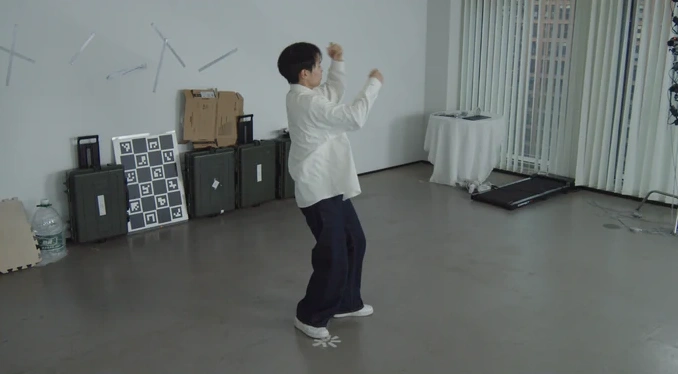
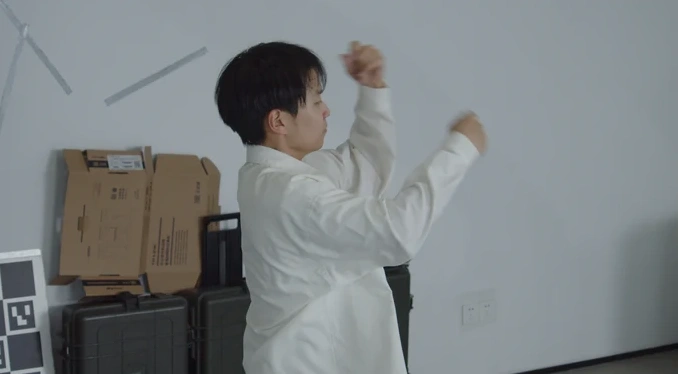
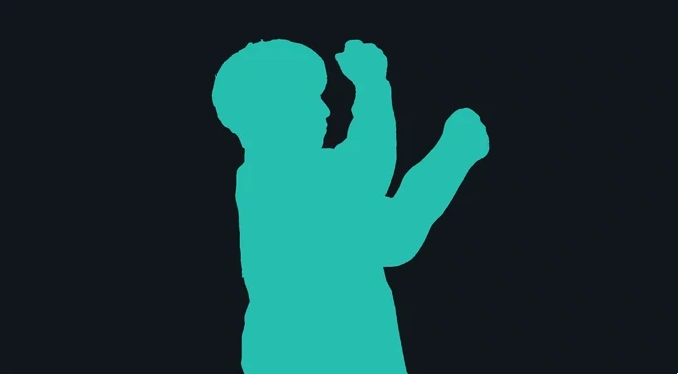
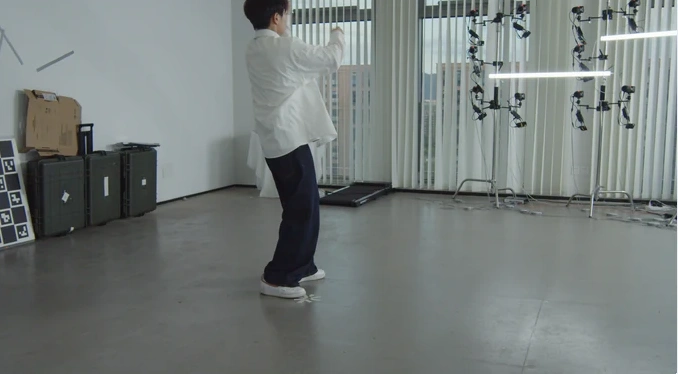
Our self-captured RealVV dataset includes varied actors, actions, scenes, camera baselines, and focal settings.
Short-focus
Long-focus
Mask
Camera rigs
Acknowledgements
We would like to thank Yujie Guo, Zhen Xu, and Taoming Liu for their insightful discussions.
This work was partially supported by the National Key R&D Program of China (No. 2024YFB2809105), the Zhejiang Provincial Natural Science Foundation of China (No. LR25F020003), and the Information Technology Center and State Key Lab of CAD&CG, Zhejiang University.
All actors shown in the dataset have authorized the use of their footage.
Citation
@inproceedings{zhou2026realme,
  title     = {RealMe: Immersive Volumetric Video from Minimal Captures},
  author    = {Zhou, Chenxu and Yu, Zhiyuan and Jin, Yudong and Shentu, Yinji and Zhang, Yu and Sun, Jiaming and Zhou, Xiaowei},
  booktitle = {SIGGRAPH Asia 2026 Conference Papers},
  year      = {2026},
  doi       = {10.1145/3829340.3842349}
}